Cloud reference
Opus 5 ULTRACODE
Cloud reference · 2 runs
- Hardware
- Cloud reference—
- Memory
- —
- Tasks
- Clair Obscure, Moorhuhn, Image recognition
- Quantisations
- —
About the model
Context window of 1 million tokens, which is both the default and the maximum; the documentation states there is no smaller context variant. Input is text and images, output is text, up to 128,000 tokens synchronously and up to 300,000 tokens via the Message Batches API with the output-300k-2026-03-24 beta header. Adaptive thinking is on by default and is steered by the effort parameter across five levels from low to max, the default is high, and thinking cannot be disabled at xhigh or max. Anthropic's model documentation states neither a parameter count nor a layer count or architecture type; what is documented is the model ID claude-opus-5, the release date of July 24, 2026, and a training data cutoff and reliable knowledge cutoff of May 2026.
- Modell-ID
- claude-opus-5
- Kontextfenster
- 1 Mio. Token (Standard und Maximum)
- Maximale Ausgabe (Messages API)
- 128K Token
- Maximale Ausgabe (Message Batches API, Beta)
- 300K Token
- Modalitäten
- Text und Bilder rein, Text raus
- Reasoning
- Adaptives Denken, standardmäßig aktiv
- Effort-Stufen
- low, medium, high, xhigh, max
- Standard-Effort
- high
Figures from the vendor: Source · Model card · Vendor
Run: Clair Obscure · 25 July 2026
The numbers at a glance
Der Lauf ging über eine fremde Schnittstelle. Es gibt kein Serverprotokoll, also weder Geschwindigkeit noch Tokenbilanz. Was zählt, ist das Artefakt.
Artefakt vorhanden und spielbar. Geschwindigkeit in der Cloud nicht vergleichbar messbar.
Results
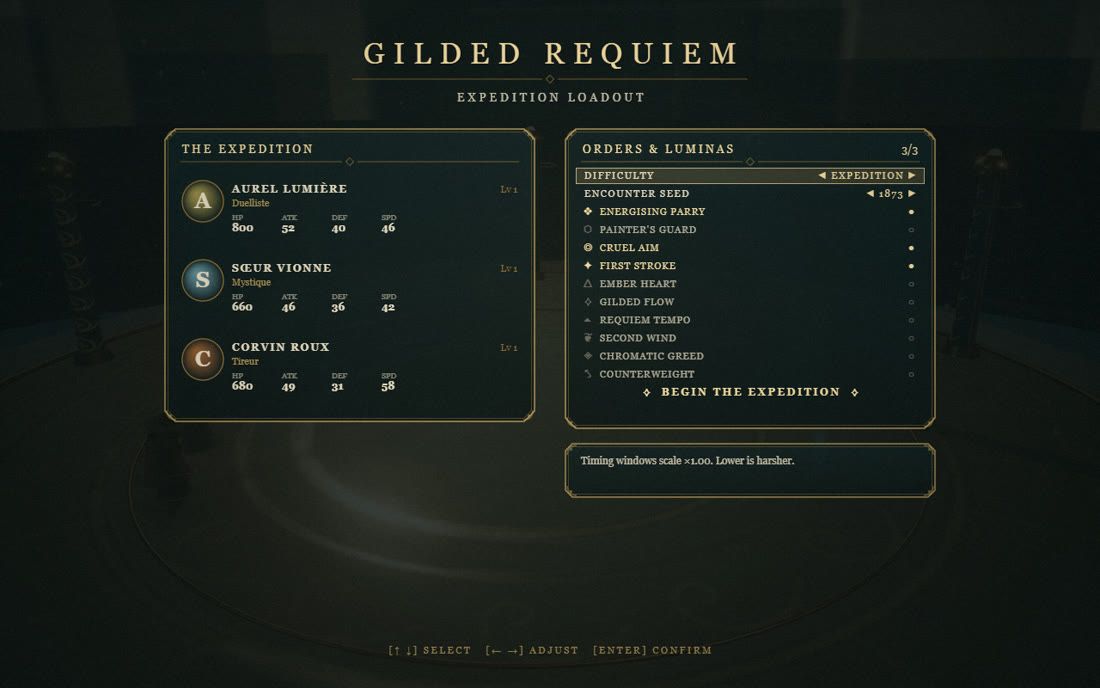
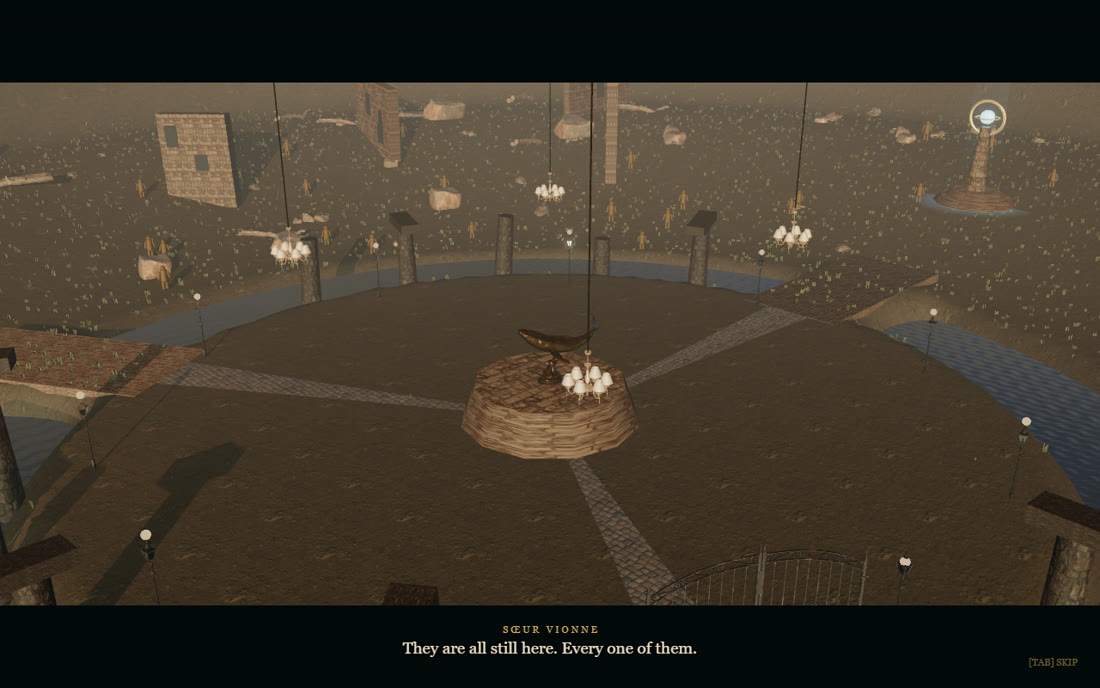
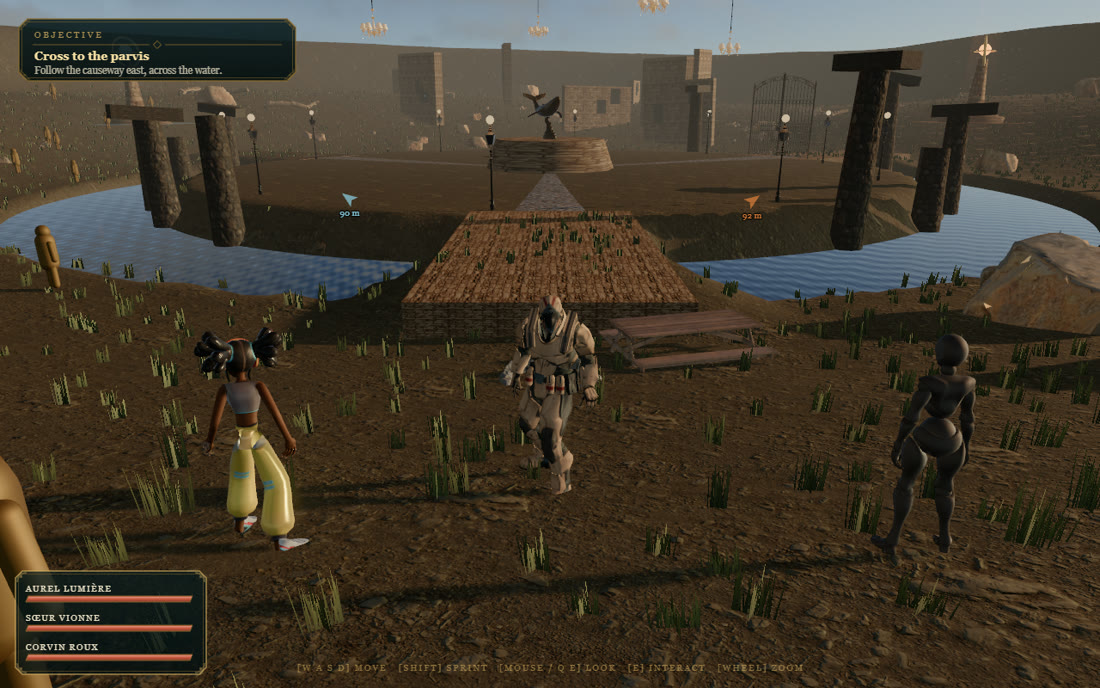
No playable build is on record for this run.
Assessment
34 / 40
The grade is a personal, and therefore subjective, assessment.
Game feelDoes it run, and does it play?
10/10
Spielbar, die vollständigste Umsetzung des Auftrags im Feld.
PresentationMenus, HUD, graphics, sound
10/10
Aufnahme mit Ladebildschirm, Kampf und Menüs.
Code qualityTests, structure, self-corrections
4/10
Keine Testdateien.
ScopeHow much of the prompt was fulfilled?
10/10
58 Dateien, 16 308 Zeilen, mit Abstand der größte Umfang.
This assessment is a proposal and has not yet been confirmed by Kai Bennett. Code quality and scope rest on counted files, source and test lines and repair scripts in the evidence repository.
How do you see it? The grade above is a personal assessment. Here yours counts, independently of it.
What went wrong
- Das Spiel lädt drei GLB-Modelle und eine 4K-HDRI nach; auf schwachen Verbindungen dauert der erste Start über zehn Sekunden.
- Eine Ressource fehlt und liefert 404 — sichtbar in der Browserkonsole, ohne Wirkung auf das Bild.
- Die Steuerung setzt Tastatur voraus. Auf Tastbildschirmen ist das Spiel nicht bedienbar.
Artefakt vorhanden und spielbar. Geschwindigkeit in der Cloud nicht vergleichbar messbar.
Run: Moorhuhn · 02 September 2026
The numbers at a glance
Dieser Lauf steht noch aus. Es liegt nur der Auftrag vor, keine Messung und kein Artefakt.
Kein Lauf, keine Zahlen.
Assessment
not yet assessed
The grade is a personal, and therefore subjective, assessment.
There is no artefact to assess for this run, so it carries no grade.
What went wrong
No self-corrections were logged.
Kein Lauf, keine Zahlen.
Image recognition
Der Lösungsschlüssel für den Bilderkennungs-Test wurde von Opus 5 selbst geschrieben. Eine eigene Trefferquote wäre zirkulär und wird deshalb nicht ausgewiesen. Der Nachbau des Diagramms steht trotzdem hier — als Beispiel dafür, was in diesem Abschnitt erwartet wird.
Sources
- Model carddocs.anthropic.com/en/docs/about-claude/models
- Vendor sitewww.anthropic.com
- Measurement repositorygithub.com/KaiFelixBennett/local-ai-amd-benchmark
- Source code · Clair Obscuregithub.com/KaiFelixBennett/local-ai-amd-benchmark/tree/main/benchmarks/opus5/clairobscure
Try it yourself
- Download the weights
- Start llama-server with the parameters above
- Register the endpoint in VS Code as a custom model and pick the agent
Prompt, agent files and tools: Agent Test Harness
Citation: Kai Felix Bennett, “Usability test of local AI on AMD hardware”, benchmark.securesight.ai, run opus5-clairobscure. Measurement data CC-BY-4.0.
Measurement data CC-BY-4.0, code MIT.