Run locally
Qwen3.8-27B
Radeon AI PRO R9700 · 3 runs
- Hardware
- Radeon AI PRO R9700gfx1201 · RDNA4
- Memory
- 32 GB dedicated
- Tasks
- Moorhuhn, Clair Obscure, Image recognition
- Quantisations
- UD-Q4_K_XL, UD-Q6_K_M
Personal opinion
Kai Bennett
For me, it is the first model I would also seriously use for coding on my own hardware. Sure, its predecessor, Qwen 3.6 27b, was already strong, but in my view this one has stepped it up quite a bit once again in terms of quality, agentic coding and the ability to review its own results. For setups between 24 and 128 GB of VRAM, it is the best model for me in September 2026.
I find it interesting that there are now also uncensored variants of it with the guardrails completely disabled, which of course has both advantages and disadvantages.
About the model
Dense model with 27 billion parameters and 262,144 tokens of native context, extensible to 1,000,000 tokens according to the model card. The card lists 64 layers with the layout 16 × (3 × (Gated DeltaNet → FFN) → 1 × (Gated Attention → FFN)), and config.json sets full_attention_interval to 4. The card gives the type as a causal language model with a vision encoder, for which config.json specifies 27 layers (field vision_config.depth). The card also mentions multi-token prediction in training, and the license is Apache 2.0.
- Architecture
- Dense (model card: “dense model”)
- Parameters
- 27B
- Layers
- 64
- Layer layout
- 16 × (3 × (Gated DeltaNet → FFN) → 1 × (Gated Attention → FFN))
- Native context
- 262,144 tokens
- Extensible context
- up to 1,000,000 tokens
- License
- Apache 2.0
Figures from the vendor: Source · Model card · Vendor
Run: Moorhuhn · UD-Q4_K_XL · reasoning xhigh · 31 August 2026
The numbers at a glance
Decode, median
33.69 t/s
82 scored responses
Decode, p10 to p90
27.83–45.34 t/s
Responses from 200 tokens up are scored; shorter ones produce outliers of over 1,000,000 t/s in the log, because a single token there takes almost zero milliseconds. Classic median, percentiles by rank. This threshold does NOT apply to prefill, where every evaluation counts.
Peak
84.92 t/s
a single response
Prefill, median
234.9 t/s
Output generated
332,405 Token
scored responses only, from 200 tokens up
Runtime
9.0 h
540 minutes
Self-corrections
4
Responses in total
108
82 of them scored
Input in total
8.04 Mio. Token
the context of all 108 requests added up
of that newly computed
503,681 Token
7.54 million were in the prompt cache
Through the model in total
8.38 Mio. Token
input and output together
At a hosting provider
1.24 USD
Qwen3.8-27B hosted, cheapest rate
What this run would have cost with Qwen3.8-27B at a hosting provider
| Provider | Inputper M | Outputper M | Cacheper M | This runwithout cache | This runwith cache |
|---|---|---|---|---|---|
| Darkbloom | 0.15 | 2.00 | · | 1.88 | · |
| Parasail | 0.24 | 2.20 | 0.050 | 2.67 | 1.24 |
| Chutes | 0.32 | 2.50 | 0.032 | 3.41 | 1.24 |
| Alibaba Cloud | 0.42 | 2.55 | 0.085 | 4.28 | 1.71 |
All amounts in USD. The first three columns are tariffs per million tokens, the last two are the total for this run. Calculated with the same tokens as on the left: 8,043,931 input across all requests, of which 503,681 were newly computed and 7,540,250 came from the prompt cache, plus 336,107 output. The “without cache” column charges the entire input at the input rate, the “with cache” column charges the cached part at the provider's cache rate. Providers with a cache rate are the norm, so the right column is the more realistic one. These are the prices for Qwen3.8-27B itself, at providers that host exactly this model, not those of some other cloud model. As of 7 September 2026, list prices without volume discounts. Locally, the run costs electricity and the purchase of the card instead. Prices at OpenRouter, retrieved 2026-09-07.
What this run would have cost with Sonnet 5 at the same token consumption
| Model | Inputper M | Outputper M | Cache writeper M | Cache readper M | This runwithout cache | This runwith cache |
|---|---|---|---|---|---|---|
| Sonnet 5 | 2.00 | 10.00 | 2.50 | 0.20 | 19.45 | 6.13 |
All amounts in USD. The first four columns are tariffs per million tokens, the last two are the total for this run. Calculated with exactly the tokens of this run: 8,043,931 input, of which 503,681 new and 7,540,250 from the cache, plus 336,107 output. Without cache at the input rate; with cache, the new part pays the write rate and the cached part the read rate. This is a comparison that assumes the same token consumption. A different model solves the same task with a different number of tokens, usually fewer; so the row says what these tokens would have cost with Sonnet 5, not what Sonnet 5 would have cost for this task. Anthropic price list, retrieved 2026-09-08.
Thinking tokens: They are contained in the output tokens but cannot be separated out. llama.cpp points this out itself at startup: “chat template supports preserving reasoning, consider enabling it via --reasoning-preserve”. The option was not set, so the log does not separate thinking from the answer.
llama.cpp server log · 82 responses from 200 tokens up. Runtime about 9 h in two sessions (31 Aug from 15:58, 1 Sep until 09:50), stopped manually at the end. The log only covers the first session (3.2 h); after that the server was restarted. · Raw log
Results
Moorland Mayhem — Featherstorm
Opens in its own layerAim and shoot with mouse or finger, R reloads. The start is behind the mode and map selection, not directly behind the first button. Needs WebGL. The first click after loading is swallowed, the second one works.
Change made by this site: The build reads localStorage without a safeguard. In the sandbox that throws an error, and the loading screen would hang. The embedded version therefore gets a substitute storage that lives only in memory; a saved game does not survive a reload. The original in the repo is unchanged.
Loads only on click · 0.3 MB transfer · 1.3 MB unpacked
Prefill over context depth
A peak figure at short context says little about how a model feels after hours. Hence the curve.
Context depth in thousands of tokens · Median per 30K band from the server log. Only evaluations from 1,000 tokens up are counted, because below that the rate depends on call overhead rather than on depth: under 300 tokens the median is 158 t/s, from 5,000 tokens up it is 333. The context position comes from pos_max, not from the number of evaluated tokens, because with prompt caching “prompt eval time” only counts what is new. 7 to 17 measurements per band, deepest position reached 140,016 tokens. There is no measurement below 20K, the prompt alone is that long.
llama.cpp launch parameters
- Context
- 262,144
- KV-Cache
- q8_0 / q8_0
- Micro-Batch
- 288
- Speculative
- draft-mtp + ngram-mod 24/48/64 · n_max 2
- Build
- b10717
llama-server -m Qwen3.8-27B-UD-Q4_K_XL.gguf ^
  --load-mode none --mmproj mmproj-F16.gguf --image-min-tokens 1024 ^
  --alias Qwen3.8-27B -dev Vulkan0 --host 127.0.0.1 --port 8080 ^
  -c 262144 -ngl 99 -fa on --fit off -ot "token_embd\.weight=Vulkan0" ^
  -ctk q8_0 -ctv q8_0 -b 2048 -ub 288 ^
  --parallel 1 --kv-unified ^
  --ctx-checkpoints 4 --checkpoint-min-step 16384 --cache-ram 0 ^
  --spec-type draft-mtp,ngram-mod --spec-draft-n-max 2 ^
  --spec-ngram-mod-n-match 24 --spec-ngram-mod-n-min 48 --spec-ngram-mod-n-max 64 ^
  --spec-draft-device Vulkan0 --spec-draft-ngl 99 ^
  --temp 1.0 --top-p 0.95 --top-k 20 --min-p 0.0 ^
  --presence-penalty 0.0 --repeat-penalty 1.0 ^
  --jinja --reasoning on --reasoning-effort xhigh --reasoning-format deepseek --reasoning-budget -1
Assessment
31 / 40
The grade is a personal, and therefore subjective, assessment.
Game feelDoes it run, and does it play?
7/10
There is a good game feel in the Moorhuhn test and it is varied, I actually have fun playing it too, even if there are a few minor flaws.
PresentationMenus, HUD, graphics, sound
7/10
Main menu with eleven entries, HUD, progress menu, the instructions are somewhat lacking, I also have to click start twice to get it going, there are still some minor bugs, but overall already impressive for a single shot.
Code qualityTests, structure, self-corrections
8/10
11 test files with 1,257 test lines, no repair scripts. The prescribed structure was implemented.
ScopeHow much of the prompt was fulfilled?
9/10
42 files, 10,838 lines; game modes, menus and statistics complete.
How do you see it? The grade above is a personal assessment. Here yours counts, independently of it.
What went wrong
There were 4 self-corrections by the model.
llama.cpp server log · 82 responses from 200 tokens up. Runtime about 9 h in two sessions (31 Aug from 15:58, 1 Sep until 09:50), stopped manually at the end. The log only covers the first session (3.2 h); after that the server was restarted.
Run: Moorhuhn · UD-Q4_K_XL · reasoning medium · 01 September 2026
The numbers at a glance
No server log, so no speed. The sequence of events comes from the chat history and the delivered source code, the runtime from the display in VS Code.
Runtime
6.5 h
388 minutes
Self-corrections
2
Second pass of the same model with the same launch line, only with --reasoning-effort medium instead of xhigh. Runtime 6 h 28 min, read by Kai Bennett from the display in VS Code. One prompt and one click on “Continue to iterate”, no other intervention. The chat history counts 95 terminal commands, 110 completed tool calls and 17 test, build or lint runs. There is no decode speed: that would require the server log, which is not available for this run.
Results
Moorland Mayhem — Featherstorm
Opens in its own layerAim and shoot with mouse or finger. Needs WebGL.
Loads only on click · — MB transfer · — MB unpacked
llama.cpp launch parameters
- Context
- 262,144
- KV-Cache
- q8_0 / q8_0
- Micro-Batch
- 288
- Speculative
- draft-mtp + ngram-mod 24/48/64 · n_max 2
- Build
- b10717
llama-server -m Qwen3.8-27B-UD-Q4_K_XL.gguf ^
  --load-mode none --mmproj mmproj-F16.gguf --image-min-tokens 1024 ^
  --alias Qwen3.8-27B -dev Vulkan0 --host 127.0.0.1 --port 8080 ^
  -c 262144 -ngl 99 -fa on --fit off -ot "token_embd\.weight=Vulkan0" ^
  -ctk q8_0 -ctv q8_0 -b 2048 -ub 288 ^
  --parallel 1 --kv-unified ^
  --ctx-checkpoints 4 --checkpoint-min-step 16384 --cache-ram 0 ^
  --spec-type draft-mtp,ngram-mod --spec-draft-n-max 2 ^
  --spec-ngram-mod-n-match 24 --spec-ngram-mod-n-min 48 --spec-ngram-mod-n-max 64 ^
  --spec-draft-device Vulkan0 --spec-draft-ngl 99 ^
  --temp 1.0 --top-p 0.95 --top-k 20 --min-p 0.0 ^
  --presence-penalty 0.0 --repeat-penalty 1.0 ^
  --jinja --reasoning on --reasoning-effort medium --reasoning-format deepseek --reasoning-budget -1
Assessment
26 / 40
The grade is a personal, and therefore subjective, assessment.
Game feelDoes it run, and does it play?
6/10
Starts and is playable, but the main menu has five entries instead of eleven.
PresentationMenus, HUD, graphics, sound
6/10
No recording available, assessed on the delivered build.
Code qualityTests, structure, self-corrections
8/10
10 test files with 604 test lines, no repair script.
ScopeHow much of the prompt was fulfilled?
6/10
44 files, 8,530 lines; modes are missing compared with the xhigh run.
This assessment is a proposal and has not yet been confirmed by Kai Bennett. Code quality and scope rest on counted files, source and test lines and repair scripts in the evidence repository.
How do you see it? The grade above is a personal assessment. Here yours counts, independently of it.
What went wrong
There were 2 self-corrections by the model.
Second pass of the same model with the same launch line, only with --reasoning-effort medium instead of xhigh. Runtime 6 h 28 min, read by Kai Bennett from the display in VS Code. One prompt and one click on “Continue to iterate”, no other intervention. The chat history counts 95 terminal commands, 110 completed tool calls and 17 test, build or lint runs. There is no decode speed: that would require the server log, which is not available for this run.
Run: Clair Obscure · UD-Q6_K_M · reasoning on, no limit · 24 August 2026
The numbers at a glance
Decode, median
26.30 t/s
30 scored responses
Decode, p10 to p90
15.55–34.22 t/s
Responses from 200 tokens up are scored; shorter ones produce outliers of over 1,000,000 t/s in the log, because a single token there takes almost zero milliseconds. Classic median, percentiles by rank. This threshold does NOT apply to prefill, where every evaluation counts.
Peak
42.39 t/s
a single response
Prefill, median
159.4 t/s
Output generated
118,919 Token
scored responses only, from 200 tokens up
Runtime
1.9 h
115 minutes
Self-corrections
6
Responses in total
35
30 of them scored
Input in total
3.24 Mio. Token
the context of all 35 requests added up
of that newly computed
293,109 Token
2.95 million were in the prompt cache
Through the model in total
3.36 Mio. Token
input and output together
At a hosting provider
0.48 USD
Qwen3.8-27B hosted, cheapest rate
What this run would have cost with Qwen3.8-27B at a hosting provider
| Provider | Inputper M | Outputper M | Cacheper M | This runwithout cache | This runwith cache |
|---|---|---|---|---|---|
| Darkbloom | 0.15 | 2.00 | · | 0.73 | · |
| Parasail | 0.24 | 2.20 | 0.050 | 1.04 | 0.48 |
| Chutes | 0.32 | 2.50 | 0.032 | 1.34 | 0.49 |
| Alibaba Cloud | 0.42 | 2.55 | 0.085 | 1.68 | 0.68 |
All amounts in USD. The first three columns are tariffs per million tokens, the last two are the total for this run. Calculated with the same tokens as on the left: 3,240,306 input across all requests, of which 293,109 were newly computed and 2,947,197 came from the prompt cache, plus 119,627 output. The “without cache” column charges the entire input at the input rate, the “with cache” column charges the cached part at the provider's cache rate. Providers with a cache rate are the norm, so the right column is the more realistic one. These are the prices for Qwen3.8-27B itself, at providers that host exactly this model, not those of some other cloud model. As of 7 September 2026, list prices without volume discounts. Locally, the run costs electricity and the purchase of the card instead. Prices at OpenRouter, retrieved 2026-09-07.
What this run would have cost with Sonnet 5 at the same token consumption
| Model | Inputper M | Outputper M | Cache writeper M | Cache readper M | This runwithout cache | This runwith cache |
|---|---|---|---|---|---|---|
| Sonnet 5 | 2.00 | 10.00 | 2.50 | 0.20 | 7.68 | 2.52 |
All amounts in USD. The first four columns are tariffs per million tokens, the last two are the total for this run. Calculated with exactly the tokens of this run: 3,240,306 input, of which 293,109 new and 2,947,197 from the cache, plus 119,627 output. Without cache at the input rate; with cache, the new part pays the write rate and the cached part the read rate. This is a comparison that assumes the same token consumption. A different model solves the same task with a different number of tokens, usually fewer; so the row says what these tokens would have cost with Sonnet 5, not what Sonnet 5 would have cost for this task. Anthropic price list, retrieved 2026-09-08.
llama.cpp server log · 30 of 35 responses from 200 tokens up · run of 28 August 2026. The server ran for 115.8 minutes in one go. From the first task to the end of the last one it is 114.9 minutes, without a single pause of more than 60 seconds in between. Of that, pure compute time on the GPU is 114.5 minutes, 88.8 minutes of it generation. · Raw log
Results
Clair Obscure — Expedition 33 (Reactive Combat Study)
Opens in its own layerMouse and keyboard. Enemy attacks are announced, parrying and dodging happen in real time. Needs WebGL.
Loads only on click · 0.4 MB transfer · 1.9 MB unpacked
Prefill over context depth
A peak figure at short context says little about how a model feels after hours. Hence the curve.
Context depth in thousands of tokens · Instantaneous rate within a single continuous prefill: task 0 of this run processed 180,396 tokens in one go. llama.cpp reports an intermediate status every 2,048 tokens; the rate is the quotient of tokens and time between two consecutive reports. There are 92 data points, seven of them are shown. Because all of them come from the same prefill, the curve is free of differences between requests. From 8K to 164K the rate drops by a factor of 4.2. Every point can be recalculated from the linked server log.
llama.cpp launch parameters
- Context
- 262,144
- KV-Cache
- q8_0 / turbo4
- Micro-Batch
- 128
- Speculative
- draft-mtp + ngram-mod · acceptance 0.553
- Build
- bd9bd1b
llama-server -m Qwen3.8-27B-UD-Q6_K_M.gguf ^
  --load-mode none --mmproj mmproj-F16.gguf --image-min-tokens 1024 ^
  -dev Vulkan0 --host 127.0.0.1 --port 8080 ^
  -c 262144 -ngl 99 -fa on --fit off -ot "token_embd\.weight=Vulkan0" ^
  -ctk q8_0 -ctv turbo4 -b 2048 -ub 128 ^
  --parallel 1 --kv-unified ^
  --ctx-checkpoints 4 --checkpoint-min-step 16384 --cache-ram 0 ^
  --spec-type draft-mtp,ngram-mod --spec-draft-n-max 2 ^
  --spec-ngram-mod-n-match 24 --spec-ngram-mod-n-min 48 --spec-ngram-mod-n-max 64 ^
  --temp 1.0 --top-p 0.95 --top-k 20 --min-p 0.0 ^
  --jinja --reasoning on --reasoning-format deepseek --reasoning-budget -1
Assessment
28 / 40
The grade is a personal, and therefore subjective, assessment.
Game feelDoes it run, and does it play?
8/10
Playable in the browser; attacks are announced, parrying and dodging happen in real time.
PresentationMenus, HUD, graphics, sound
8/10
Recording available, combat HUD complete.
Code qualityTests, structure, self-corrections
4/10
No test files; six logged self-corrections.
ScopeHow much of the prompt was fulfilled?
8/10
36 files, 11,115 lines, the most extensive Clair Obscure run on local hardware.
This assessment is a proposal and has not yet been confirmed by Kai Bennett. Code quality and scope rest on counted files, source and test lines and repair scripts in the evidence repository.
How do you see it? The grade above is a personal assessment. Here yours counts, independently of it.
What went wrong
There were 6 self-corrections by the model.
llama.cpp server log · 30 of 35 responses from 200 tokens up · run of 28 August 2026. The server ran for 115.8 minutes in one go. From the first task to the end of the last one it is 114.9 minutes, without a single pause of more than 60 seconds in between. Of that, pure compute time on the GPU is 114.5 minutes, 88.8 minutes of it generation.
Image recognition
A separate test run with the same model on the same machine, part of a different run. The time was noted from the VS Code chat display.
Values read
44 of 50
dashboard, 50 checkable entries
Price tags
2 of 4
read fully correctly
Invented tags
4
1 of them claimed as certain
Traps passed
2 of 4
places that break the pattern
Provisional: the answer key for the price tags is not fully confirmed yet.
Task 1 · reading values
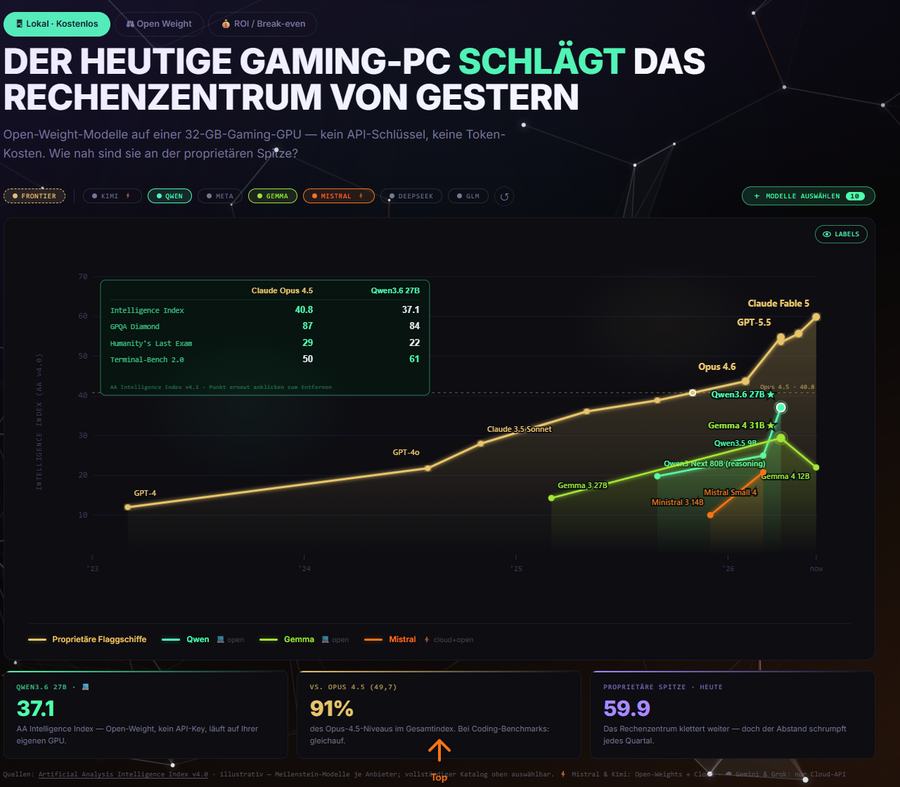
What the model read from the tooltip table
| Claude Opus 4.5 | Qwen3.6 27B | |
|---|---|---|
| Intelligence Index | 40.8 | 37.1 |
| GPQA Diamond | 87 | 84 |
| Humanity's Last Exam | 29 | 22 |
| Terminal-Bench 2.0 | 50 | 61 |
And from the KPI tiles
- QWEN3.6 27B · OPEN 37.1 · AA Intelligence Index — Open-Weight, kein API-Key, läuft auf ihrer eigenen GPU.
- VS. OPUS 4.5 (40,7) 91% · des Opus-4.5-Niveaus im Gesamtindex. Bei Coding-Benchmarks: gleichauf.
- PROPRIETÄRE SPIEZE · HEUTE 59.9 · Das Rechenzentrum klettert weiter — doch der Abstand schrumpft jedes Quartal.
Task 2 · complex text recognition
What is tested is the reading of tiny, tilted, partly hidden text in a photo with more than forty objects, plus two currency symbols that are hard to tell apart once rotated. The price tags are what the test is run on.
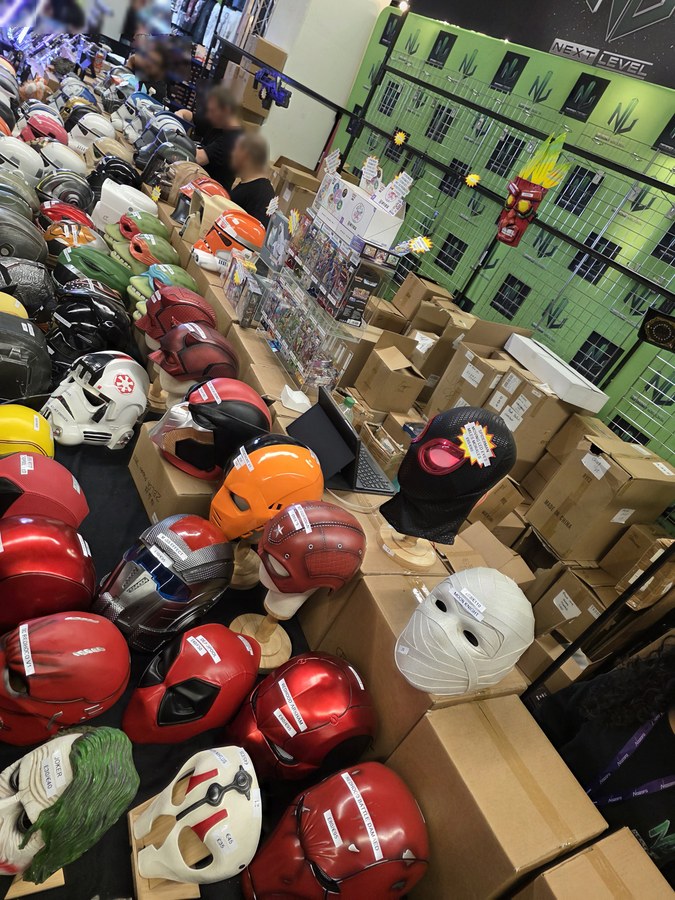
What the model read
| What the model read there | £ | € | Order | certain | |
|---|---|---|---|---|---|
| 1 | REDHOOD ARKHAM | 80 | 65 | gbp zuerst | yes |
| 2 | JOKER | 50 | 40 | gbp zuerst | no |
| 3 | unnamed | 45 | 35 | gbp zuerst | yes |
| 4 | REDHOOD (BATTL) DARK RED | 80 | 65 | gbp zuerst | no |
| 5 | BANE | not readable | not readable | · | no |
| 6 | HULK | not readable | not readable | · | no |
| 7 | BATMAN | not readable | not readable | · | no |
The model counted 7 tags in the scored area. The answer key is deliberately not shown beside it, otherwise a later model could read it off this page.
The model on the hardest part: „Der dicht beieinander liegende Datenpunkt-Cluster im rechten Diagrammbereich (Qwen/Gemma/Mistral-Labels überlappen) und die kleinen Währungssymbole auf den schräg stehenden Preisschildern in Bild B (€ vs. £ kaum unterscheidbar).“
Where the model called itself unsure (9 places)
- Bild A: zweiter X-Achsen-Tick — ich lese '24', nicht ausschließen, dass es '23 ist
- Bild A: Y-Achsenlabel hinter 'INTELLIGENZ-INDEX (…)' nicht vollständig lesbar
- Bild A: Kachel 2, Klammerwert liest sich wie '(40,7)', passt aber nicht zu '40.8' im Tooltip — möglicher Lesefehler
- Bild A: Fußzeile des Tooltips nur teilweise lesbar
- Bild A: grauer Legendeneintrag rechts ('Claude+open'?) unscharf
- Bild B: JOKER-Schild — zweites Währungssymbol (£ oder €?)
- Bild B: REDHOOD (BATTL) DARK RED — zweites Währungssymbol unsicher
- Bild B: Namen BANE, HULK, BATMAN sind Vermutungen; dazugehörige Preise nicht lesbar (null statt Raten)
- Bild B: ob das rote Klebeschild am orangefarbenen Helm (ca. y 890–955) noch in den Wertungsbereich fällt, war grenzwertig
The model wrote this list itself, not the scorer. It counts: an admitted “not readable” costs one point, an invented entry costs more.
The complete answer of the model as JSON · The scoring is not published beside it: it names the correct value for every mistake, which would put the answer key in the open.
Sources
- Model weightshuggingface.co/unsloth/Qwen3.8-27B-GGUF
- Model cardhuggingface.co/Qwen/Qwen3.8-27B
- Vendor siteqwen.ai
- Measurement repositorygithub.com/KaiFelixBennett/local-ai-amd-benchmark
- Raw log of this rungithub.com/KaiFelixBennett/local-ai-amd-benchmark/blob/main/evidence/logs/qwen38-27b-q4xl-moorhuhn-r9700.log
- Source code · Moorhuhn · UD-Q4_K_XL · Reasoning xhighgithub.com/KaiFelixBennett/local-ai-amd-benchmark/tree/main/benchmarks/qwen38-27b/moorhuhn-q4xl-xhigh
- Source code · Moorhuhn · UD-Q4_K_XL · Reasoning mediumgithub.com/KaiFelixBennett/local-ai-amd-benchmark/tree/main/benchmarks/qwen38-27b/moorhuhn-q4xl-medium
- Source code · Clair Obscure · UD-Q6_K_M · Reasoning on, no limitgithub.com/KaiFelixBennett/local-ai-amd-benchmark/tree/main/benchmarks/qwen38-27b/clairobscure-q6
Try it yourself
- Download the weights · Source
- Start llama-server with the parameters above
- Register the endpoint in VS Code as a custom model and pick the agent
Prompt, agent files and tools: Agent Test Harness
Citation: Kai Felix Bennett, “Usability test of local AI on AMD hardware”, benchmark.securesight.ai, run qwen38-27b-q4xl-moorhuhn-r9700. Measurement data CC-BY-4.0.
Measurement data CC-BY-4.0, code MIT.