Cloud reference
Sonnet 5
Cloud reference
- Hardware
- Cloud reference—
- Memory
- —
- Tasks
- Moorhuhn, Image recognition
- Quantisations
- —
About the model
Anthropic publishes no architecture data for Claude Sonnet 5. Neither the Claude platform model page nor the system card of June 30, 2026 states a parameter count, a layer count, or whether the model is dense or built as a mixture of experts. Only operating data is documented: a 1 million token context window, 128,000 tokens maximum output, text and images as input, text as output, adaptive thinking with five effort levels, and a training data cutoff in January 2026. The system card describes the training as a proprietary mix of publicly available information from the internet, public and private datasets, and synthetic data generated by other models, with no figures for compute or data volume.
- Modell-ID
- claude-sonnet-5
- Kontextfenster
- 1 000 000 Token
- Maximale Ausgabe
- 128 000 Token
- Maximale Ausgabe (Batch API, Beta)
- 300 000 Token
- Ein- und Ausgabe
- Text und Bilder zu Text
- Denkmodus
- Adaptives Denken, standardmäßig aktiv
- Effort-Stufen
- low, medium, high, xhigh, max; Standard high
- Tokenizer
- Rund 30 Prozent mehr Token je Text als bei Sonnet 4.6
Figures from the vendor: Source · Model card · Vendor
The numbers at a glance
Der Lauf ging über eine fremde Schnittstelle. Es gibt kein Serverprotokoll, also weder Geschwindigkeit noch Tokenbilanz. Was zählt, ist das Artefakt.
Runtime
1.2 h
70 minutes
Self-corrections
2
Cloud-Referenz über die Anthropic-API. Das Artefakt liegt vor, die Geschwindigkeit ist nicht vergleichbar gemessen. Die Laufzeit von rund 70 Minuten ist aus der Sitzung notiert, nicht aus einem Protokoll gerechnet.
Results
Moorland Mayhem — Featherstorm
Opens in its own layerZielen und schießen mit Maus oder Finger. Braucht WebGL.
Loads only on click · 0.3 MB transfer · 1.6 MB unpacked
Assessment
32 / 40
The grade is a personal, and therefore subjective, assessment.
Game feelDoes it run, and does it play?
8/10
Spielbar, Cloud-Referenz mit hoher Reasoning-Stufe.
PresentationMenus, HUD, graphics, sound
8/10
Aufnahme vorhanden.
Code qualityTests, structure, self-corrections
8/10
12 Testdateien, kein Reparaturskript.
ScopeHow much of the prompt was fulfilled?
8/10
72 Dateien, 9 433 Zeilen.
This assessment is a proposal and has not yet been confirmed by Kai Bennett. Code quality and scope rest on counted files, source and test lines and repair scripts in the evidence repository.
How do you see it? The grade above is a personal assessment. Here yours counts, independently of it.
What went wrong
There were 2 self-corrections by the model.
Cloud-Referenz über die Anthropic-API. Das Artefakt liegt vor, die Geschwindigkeit ist nicht vergleichbar gemessen. Die Laufzeit von rund 70 Minuten ist aus der Sitzung notiert, nicht aus einem Protokoll gerechnet.
Image recognition
Eigener Testlauf, nicht Teil eines gemessenen Laufs. Cloud-Referenz.
Values read
46 of 50
dashboard, 50 checkable entries
Price tags
1 of 4
read fully correctly
Invented tags
5
none claimed as certain
Traps passed
2 of 4
places that break the pattern
Provisional: the answer key for the price tags is not fully confirmed yet.
Task 1 · reading values
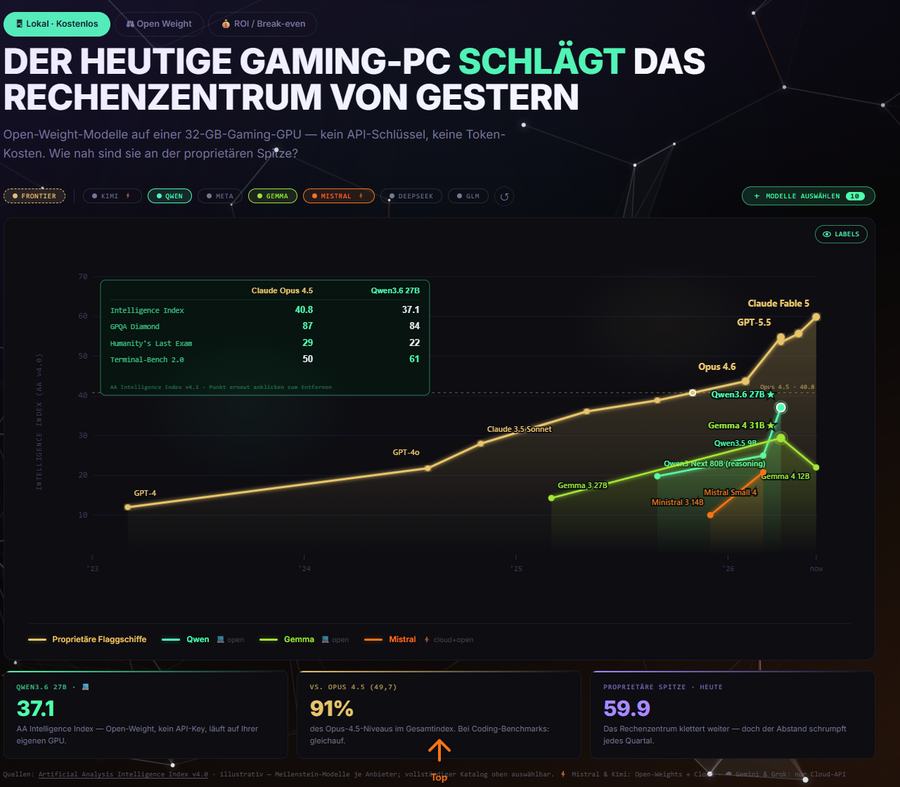
What the model read from the tooltip table
| Claude Opus 4.5 | Qwen3.6 27B | |
|---|---|---|
| Intelligence Index | 40.8 | 37.1 |
| GPQA Diamond | 87 | 84 |
| Humanity's Last Exam | 29 | 22 |
| Terminal-Bench 2.0 | 50 | 61 |
And from the KPI tiles
- QWEN3.6 27B · OPEN 37.1 · AA Intelligence Index — Open-Weight, kein API-Key, läuft auf ihrer eigenen GPU.
- VS. OPUS 4.5 (40,8) 91% · des Opus-4.5-Niveaus im Gesamtindex. Bei Coding-Benchmarks: gleichauf.
- PROPRIETÄRE SPITZE · HEUTE 59.9 · Das Rechenzentrum klettert weiter — doch der Abstand schrumpft jedes Quartal.
Task 2 · complex text recognition
What is tested is the reading of tiny, tilted, partly hidden text in a photo with more than forty objects, plus two currency symbols that are hard to tell apart once rotated. The price tags are what the test is run on.
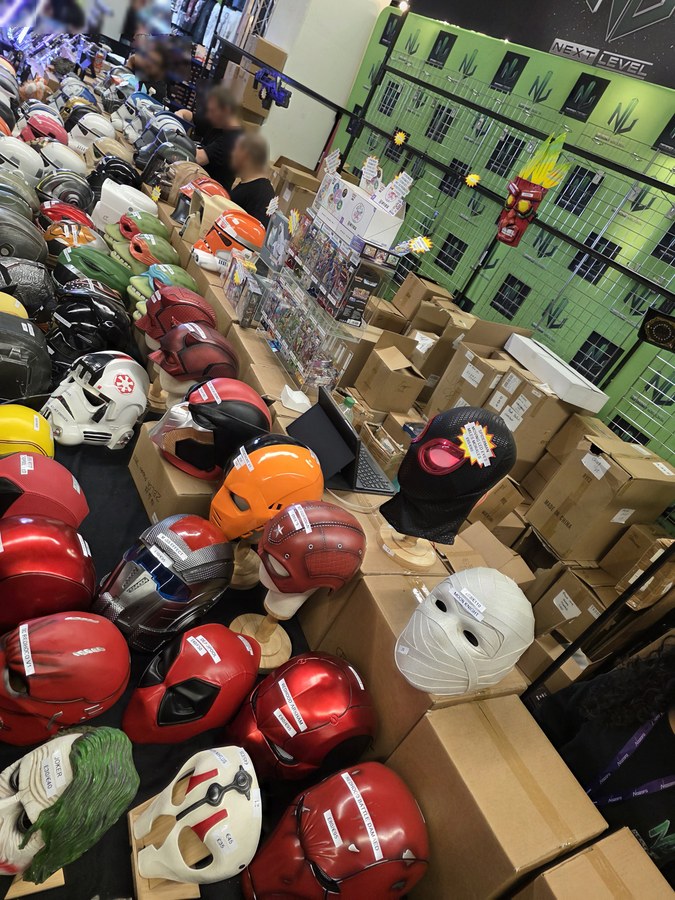
What the model read
| What the model read there | £ | € | Order | certain | |
|---|---|---|---|---|---|
| 1 | MASS EFFECT | not readable | not readable | · | no |
| 2 | JOKER | 30 | 40 | gbp zuerst | no |
| 3 | unnamed | 45 | 35 | eur zuerst | no |
| 4 | unnamed | not readable | not readable | · | no |
| 5 | unnamed | not readable | not readable | · | no |
| 6 | unnamed | not readable | not readable | · | no |
The model counted 8 tags in the scored area. The answer key is deliberately not shown beside it, otherwise a later model could read it off this page.
The model on the hardest part: „Im Diagramm die eng gedrängten Punktbeschriftungen oben rechts (Qwen-, Gemma- und Mistral-Punkte liegen dicht beieinander, Labels überschneiden sich fast). In Bild B die Preisziffern selbst: die Schilder liegen schräg zur Kamera und sind bei mehreren Masken so klein/unscharf abgebildet, dass ich nicht einmal den vollständigen Produktnamen sicher lesen konnte, geschweige denn die Beträge.“
Where the model called itself unsure (10 places)
- Bild A: erster X-Achsen-Wert — gelesen als '23, könnte auch '22 sein
- Bild A: Klammerwert in Kachel 2 — gelesen als '(40,8)', Ziffer nicht eindeutig
- Bild A: Y-Achsenbeschriftung '(AA v4.0)' im Klammerteil unsicher
- Bild A: Fußzeile unter der Tooltip-Tabelle nur teilweise lesbar
- Bild A: mögliche kleine Zahlen-Abzeichen neben KIMI und MISTRAL im Filter — Ziffern zu klein für eine sichere Lesung
- Bild A: Zusatztext neben dem Mistral-Legendeneintrag nicht sicher entzifferbar
- Bild B: bei den meisten Schildern im Wertungsbereich waren die Pfund-/Euro-Ziffern zu klein bzw. zu schräg fotografiert, um sie ohne Raten zu übernehmen — deshalb dort null statt einer erfundenen Zahl
- Bild B: Reihenfolge £/€ bei mehreren Schildern nicht sicher bestimmbar
- Bild B: genaue Zusatzbezeichnungen der drei 'REDHOOD'-Masken (z. B. V1 / Armor / Battle Damaged / Airman) nicht sicher unterscheidbar
- Bild B: die Abgrenzung des Wertungsbereichs (x bis 700, y ab 950) konnte ich nur optisch schätzen, ohne Koordinatenwerkzeug — einzelne Schilder nahe der Grenze könnten falsch zugeordnet sein
The model wrote this list itself, not the scorer. It counts: an admitted “not readable” costs one point, an invented entry costs more.
The complete answer of the model as JSON · The scoring is not published beside it: it names the correct value for every mistake, which would put the answer key in the open.
Sources
- Model carddocs.anthropic.com/en/docs/about-claude/models
- Vendor sitewww.anthropic.com
- Measurement repositorygithub.com/KaiFelixBennett/local-ai-amd-benchmark
- Source code · Moorhuhngithub.com/KaiFelixBennett/local-ai-amd-benchmark/tree/main/benchmarks/sonnet5/moorhuhn
Try it yourself
- Download the weights
- Start llama-server with the parameters above
- Register the endpoint in VS Code as a custom model and pick the agent
Prompt, agent files and tools: Agent Test Harness
Citation: Kai Felix Bennett, “Usability test of local AI on AMD hardware”, benchmark.securesight.ai, run sonnet5. Measurement data CC-BY-4.0.
Measurement data CC-BY-4.0, code MIT.