Run locally
Qwen3.8-Flash-Next
AMD AI MAX 395 (AMD Halo) · GMKtec EVO-X2 · 3 runs
- Hardware
- AMD AI MAX 395 (AMD Halo) · GMKtec EVO-X2Strix Halo · Radeon 8060S · gfx1151
- Memory
- 128 GiB unified
- Tasks
- Moorhuhn, Clair Obscure, Image recognition
- Quantisations
- UD-Q4_K_XL, W4B
Personal opinion
Kai Bennett
Until now I had not found a model that works really well on the AMD Strix Halo, because either they were dense models that ran too slowly with the low bandwidth, or they were so small that they also ran well on hardware with much less memory, or they had, for example, no image recognition capabilities.
This model changes that. In the benchmarks it can keep up with much larger models and is even ranked above GPT 5.6 Luna (max) at artificialanalysis.ai, it runs consistently at around 20 tokens even with larger context, has vision capabilities, uses the full memory of the device and delivers good results.
In my view, the model is practically made for the AMD Strix Halo or DGX Spark.
About the model
Hybrid MoE model with 125 billion parameters in the language model, 6 billion of them active per token, plus 51 billion parameters of n-gram embedding and 4 billion MTP. The model card states 48 layers in the pattern 12 × (3 × (Gated DeltaNet → MoE) → 1 × (Qwen Sparse Attention → MoE)) and 512 experts, of which 10 routed and 1 shared are active per token. Native context is 262,144 tokens and can be extended to 1,000,000 tokens. The type is given as "Causal Language Model with Vision Encoder", and config.json contains a vision encoder with 27 layers and hidden size 1152.
- Total parameters, language model
- 125B
- Active parameters per token
- 6B
- N-gram embedding
- 51B
- MTP
- 4B, 1 layer
- Layers
- 48
- Layer pattern
- 12 × (3 × (Gated DeltaNet → MoE) → 1 × (Qwen Sparse Attention → MoE))
- Experts
- 512
- Active experts
- 10 routed + 1 shared
- Context length
- 262,144 native, extensible to 1,000,000 tokens
- License
- other, license_name qwen-community-1.0
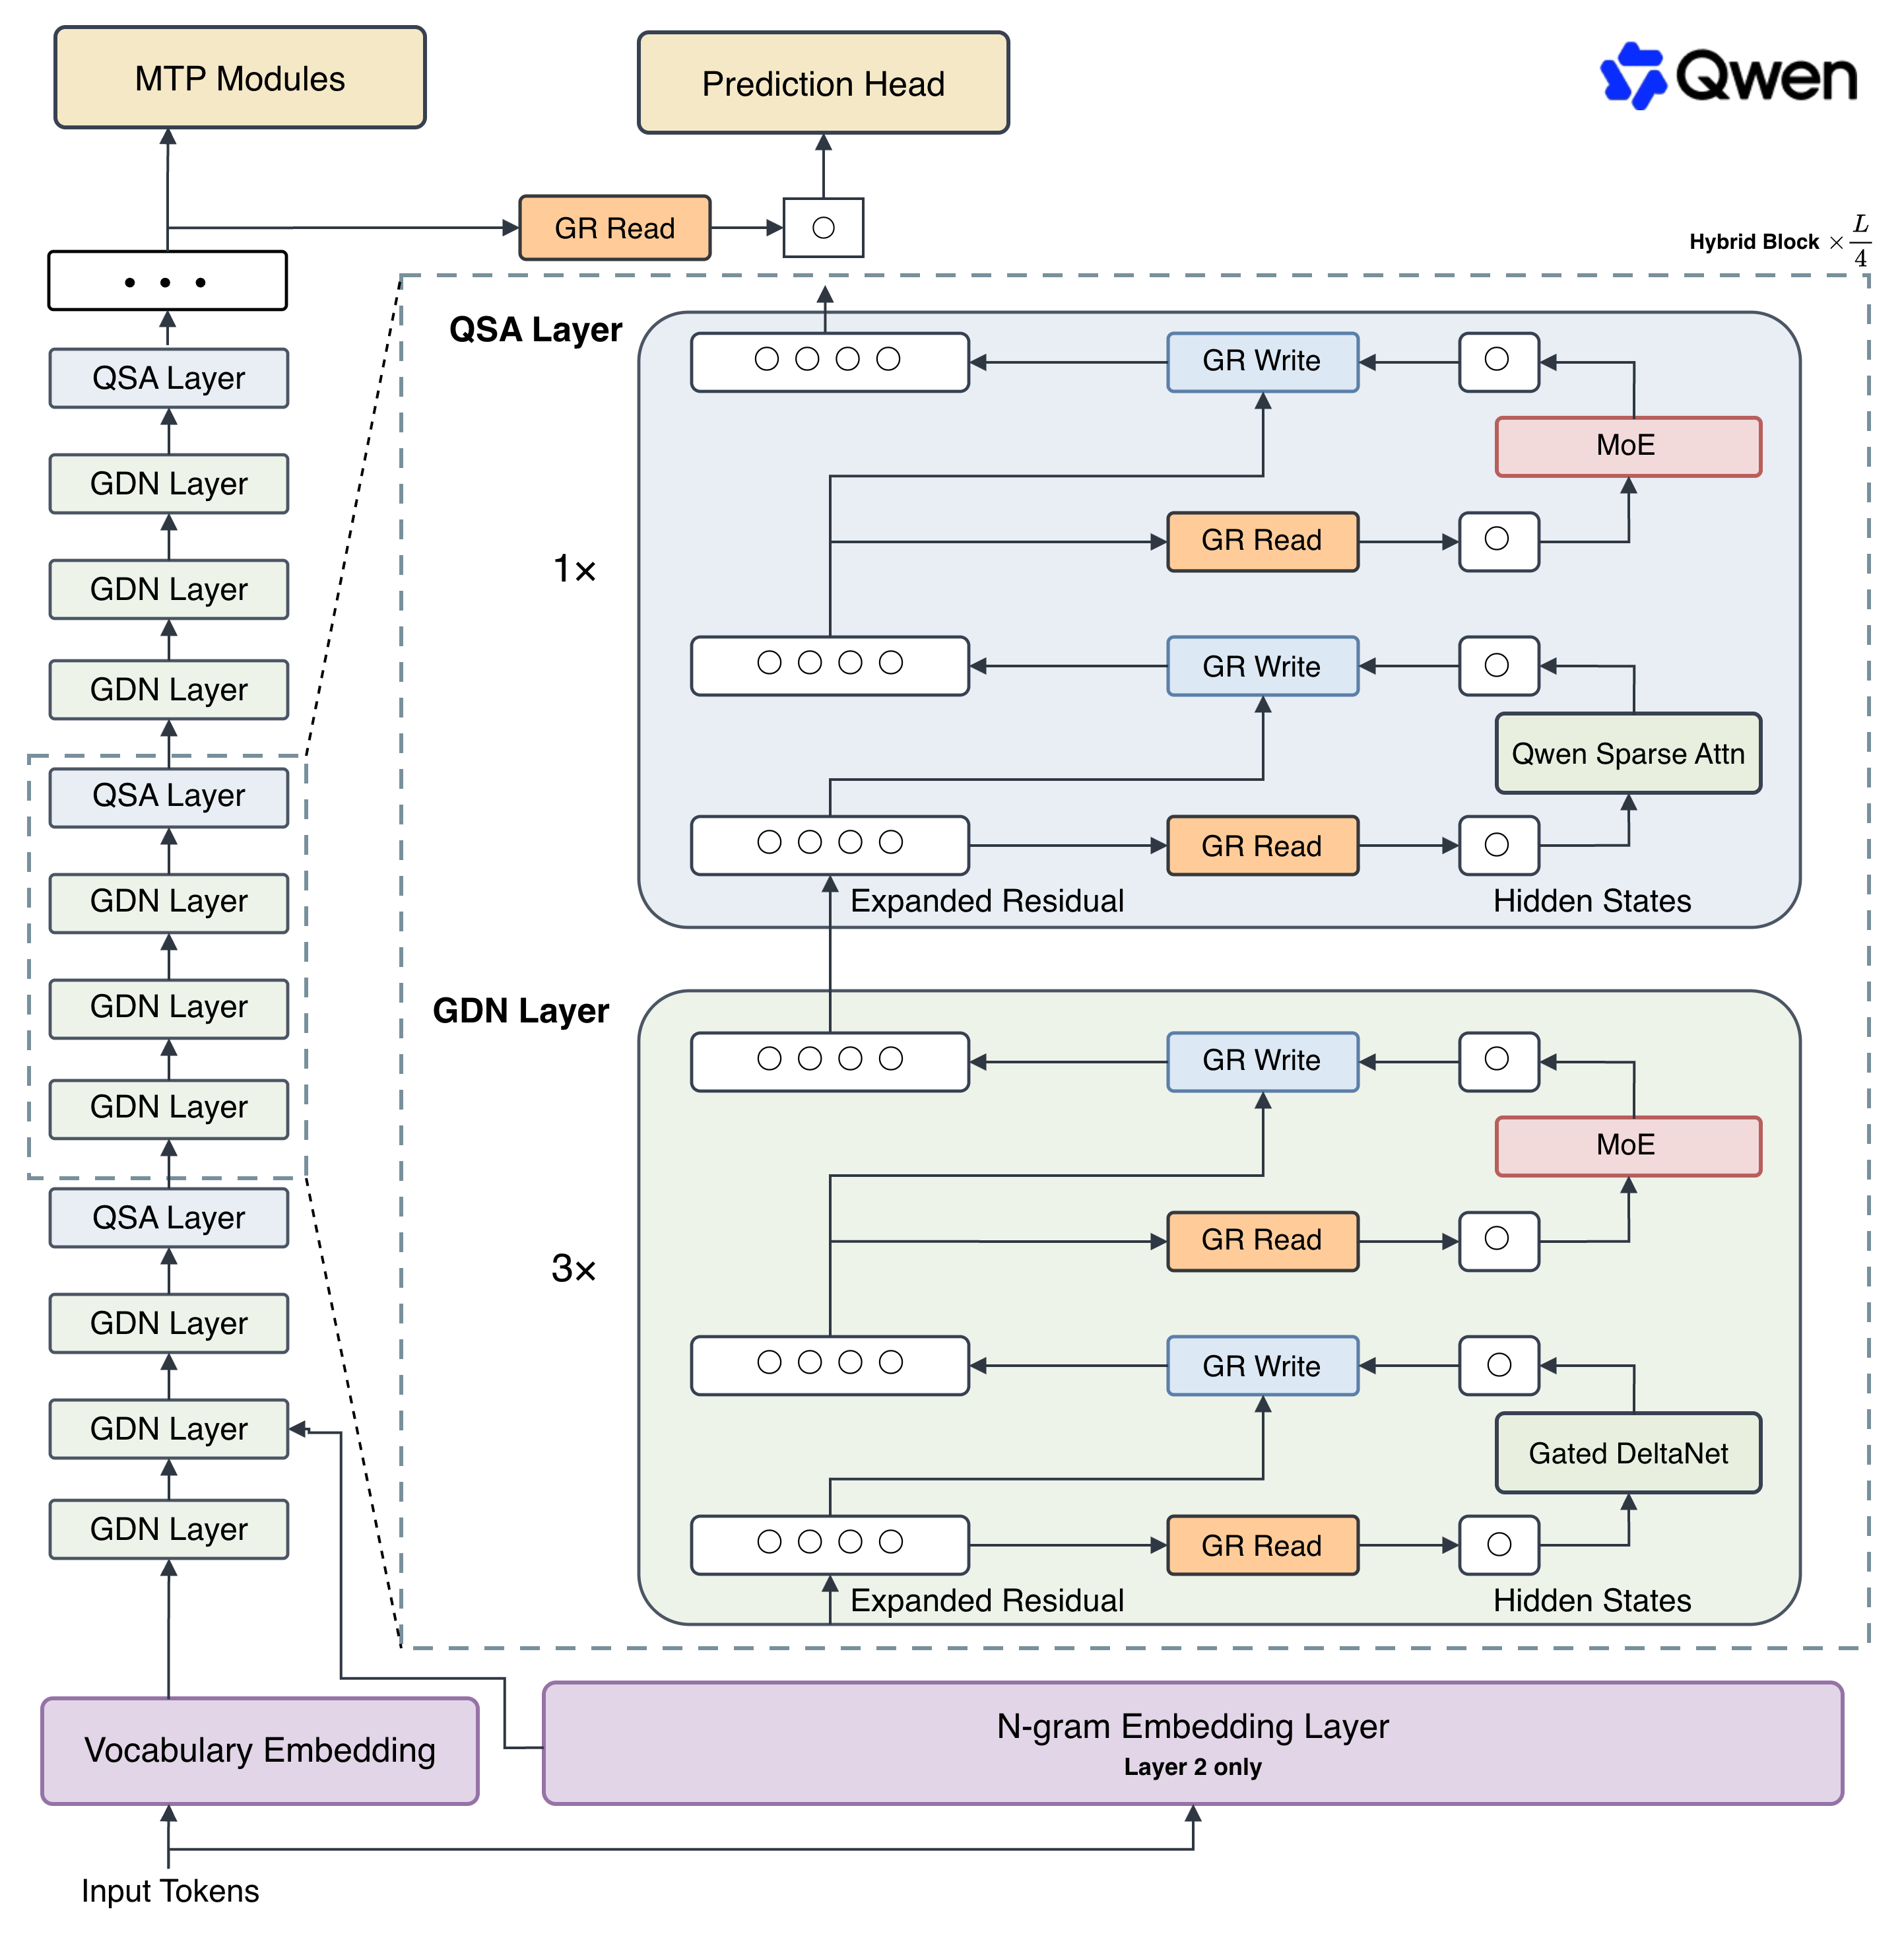
Figures from the vendor: Source · Model card · Vendor
Run: Moorhuhn · UD-Q4_K_XL · reasoning xhigh · 03 September 2026
The numbers at a glance
Decode, median
21.76 t/s
346 scored responses
Decode, p10 to p90
17.15–26.28 t/s
Responses from 200 tokens up are scored; shorter ones produce outliers of over 1,000,000 t/s in the log, because a single token there takes almost zero milliseconds. Classic median, percentiles by rank. This threshold does NOT apply to prefill, where every evaluation counts.
Peak
33.89 t/s
a single response
Prefill, median
77.6 t/s
Output generated
770,428 Token
scored responses only, from 200 tokens up
Runtime
13.6 h
815 minutes
Self-corrections
not measured
Responses in total
459
346 of them scored
Input in total
24.15 Mio. Token
the context of all 459 requests added up
of that newly computed
1,051,292 Token
23.10 million were in the prompt cache
Through the model in total
24.94 Mio. Token
input and output together
At a hosting provider
0.95 USD
Qwen3.8 Flash hosted, cheapest rate
What this run would have cost with Qwen3.8 Flash at a hosting provider
| Provider | Inputper M | Outputper M | Cacheper M | This runwithout cache | This runwith cache |
|---|---|---|---|---|---|
| Alibaba Cloud Int. | 0.15 | 0.47 | 0.016 | 3.99 | 0.95 |
All amounts in USD. The first three columns are tariffs per million tokens, the last two are the total for this run. Calculated with the same tokens as on the left: 24,148,766 input across all requests, of which 1,051,292 were newly computed and 23,097,474 came from the prompt cache, plus 786,506 output. The “without cache” column charges the entire input at the input rate. In the “with cache” column, the new part pays the write rate of 0.20 USD and the cached part the read rate of 0.016 USD. The only provider is Alibaba Cloud International. There the model is called “Qwen3.8 Flash”, without the suffix Next and without a parameter count. What ran here is the Qwen3.8-Flash-Next build from Hugging Face with 125 billion parameters, 6 billion of them active. The same vendor, the same context length of 1,000,000 tokens and the same release date point to the same origin; the provider page does not prove it. As of 8 September 2026, list prices without volume discounts. Locally, the run costs electricity and the purchase of the computer instead. Prices at OpenRouter, retrieved 2026-09-08.
What this run would have cost with Sonnet 5 at the same token consumption
| Model | Inputper M | Outputper M | Cache writeper M | Cache readper M | This runwithout cache | This runwith cache |
|---|---|---|---|---|---|---|
| Sonnet 5 | 2.00 | 10.00 | 2.50 | 0.20 | 56.16 | 15.11 |
All amounts in USD. The first four columns are tariffs per million tokens, the last two are the total for this run. Calculated with exactly the tokens of this run: 24,148,766 input, of which 1,051,292 new and 23,097,474 from the cache, plus 786,506 output. Without cache at the input rate; with cache, the new part pays the write rate and the cached part the read rate. This is a comparison that assumes the same token consumption. A different model solves the same task with a different number of tokens, usually fewer; so the row says what these tokens would have cost with Sonnet 5, not what Sonnet 5 would have cost for this task. Anthropic price list, retrieved 2026-09-08.
llama.cpp server log · 346 of 459 responses from 200 tokens up · run of 3/4 September 2026, 13 h 35 min. The server ran for 844.3 minutes in one go. From the first task to the end of the last one it is 837.0 minutes; this includes one idle pause of 21.9 minutes. The working window is therefore 815 minutes. Pure compute time on the GPU is 798.8 minutes. · Raw log
Results
Moorland Mayhem — Featherstorm
Opens in its own layerAim and shoot with mouse or finger. Reloading happens automatically in five of seven modes. Needs WebGL. In portrait mode the targets are smaller than a fingertip, so play in landscape in full screen.
Loads only on click · 0.3 MB transfer · 1.3 MB unpacked
Prefill over context depth
A peak figure at short context says little about how a model feels after hours. Hence the curve.
Context depth in thousands of tokens · Instantaneous rate within a single continuous prefill: task 185882 of this run processed 69,985 tokens in one go. llama.cpp reports an intermediate status every 2,048 tokens; the rate is the quotient of tokens and time between two consecutive reports. 32 steps remain, values under 1,500 tokens are excluded. From 2,048 to 68,827 tokens the rate drops by a factor of 1.58. Every point can be traced in the linked server log.
llama.cpp launch parameters
- Context
- 131,072
- KV-Cache
- q8_0 / q8_0
- Micro-Batch
- 512
- Speculative
- MTP, Shared-Q8_0, n-max 2
- Build
- —
llama-server ^
  -m Qwen3.8-Flash-Next-UD-Q4_K_XL-00001-of-00004.gguf ^
  -md mtp-Qwen3.8-Flash-Next-shared-Q8_0.gguf ^
  --spec-type draft-mtp --spec-draft-n-max 2 ^
  --mmproj mmproj-F16.gguf --alias qwen3.8-flash-next ^
  --host 127.0.0.1 --port 8099 --device Vulkan0 --gpu-layers all ^
  --n-cpu-moe 0 --fit off -fa on --load-mode mmap --lazy-mode on ^
  --ctx-size 131072 --parallel 1 --kv-unified ^
  -ctk q8_0 -ctv q8_0 -b 2048 -ub 512 ^
  --ctx-checkpoints 4 --checkpoint-min-step 4096 --jinja ^
  --reasoning on --reasoning-format deepseek ^
  --reasoning-effort xhigh --reasoning-budget 12000 ^
  --temp 1.0 --top-p 0.95 --top-k 20 --min-p 0.0 ^
  --presence-penalty 0.0 --repeat-penalty 1.0
Assessment
34 / 40
The grade is a personal, and therefore subjective, assessment.
Game feelDoes it run, and does it play?
9/10
A very good game feel and feedback, playing is fun and varied.
PresentationMenus, HUD, graphics, sound
9/10
Complete implementations, menus are nicely and extensively designed. Best result, better than Sonnet 5.
Code qualityTests, structure, self-corrections
7/10
12 test files with 1,494 test lines, no repair script. Sensible folder structure, it also created a subfolder. Consistent layering. Some settings do not work.
ScopeHow much of the prompt was fulfilled?
9/10
55 files, 10,531 lines. Almost everything from the prompt was actually implemented in the game.
How do you see it? The grade above is a personal assessment. Here yours counts, independently of it.
What went wrong
- The loading screen says “Featherstorm wordt geladen”, Dutch instead of German. Exactly one spot in the whole game; the rest is German throughout.
- The game renders to a 1280×720 canvas. On a phone 390 pixels wide it is scaled down to 390×219, playable, but the targets are small.
- The run needed three sessions (20, 376 and 419 minutes). Between the sessions the context was lost and had to be rebuilt.
llama.cpp server log · 346 of 459 responses from 200 tokens up · run of 3/4 September 2026, 13 h 35 min. The server ran for 844.3 minutes in one go. From the first task to the end of the last one it is 837.0 minutes; this includes one idle pause of 21.9 minutes. The working window is therefore 815 minutes. Pure compute time on the GPU is 798.8 minutes.
Image recognition
Repeated on 18 September 2026 with the original images, not part of the run that built the game. The first test that morning is invalid: it got a scaled-down version of image B, and the agent's tool restriction did not take effect.
Values read
41 of 50
dashboard, 50 checkable entries
Price tags
2 of 4
read fully correctly
Invented tags
4
1 of them claimed as certain
Stumbling points spotted
1 of 4
places that break the pattern
Provisional: the answer key for the price tags is not fully confirmed yet.
Task 1 · reading values
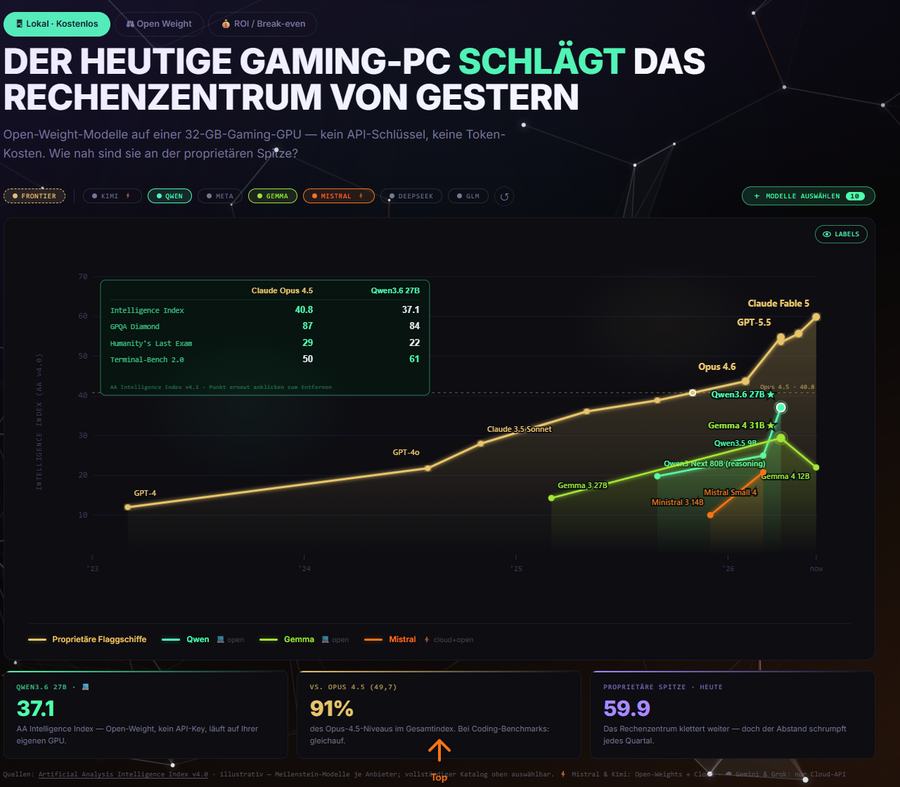
What the model read from the tooltip table
| Claude Opus 4.5 | Qwen3.6 27B | |
|---|---|---|
| Intelligence Index | 40.8 | 37.1 |
| GPQA Diamond | 87 | 84 |
| Humanity's Last Exam | 29 | 22 |
| Terminal-bench 2.0 | 50 | 61 |
And from the KPI tiles, in German as on the test image
- QWEN3.6 27B 37.1 · AA Intelligence Index — Open-Weight, kein API-Key, läuft auf deiner eigenen GPU.
- VS. OPUS 4.5 (40,8) 91% · des Opus-4.5-Niveaus im Gesamtindex. Bei Coding-Benchmarks gleichauf.
- PROPRIETÄRE SPITZE - HEUTE 59.9 · Das Rechenzentrum klettert weiter — doch der Abstand schrumpft jedes Quartal.
Task 2 · complex text recognition
What is tested is the reading of tiny, tilted, partly hidden text in a photo with more than forty objects, plus two currency symbols that are hard to tell apart once rotated. The price tags are what the test is run on.
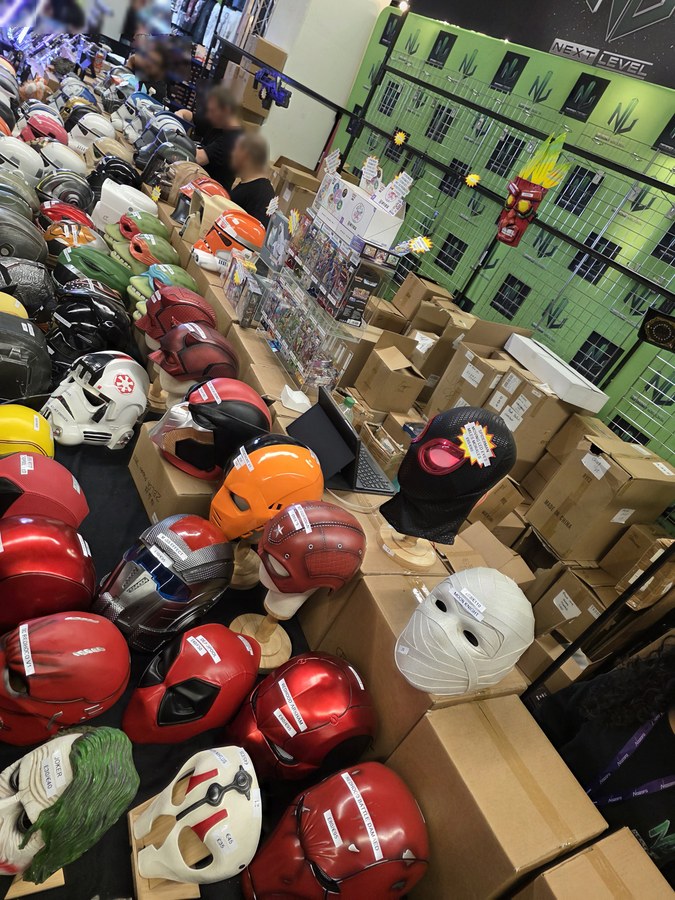
What the model read
| What the model read there | £ | € | Order | certain | |
|---|---|---|---|---|---|
| 1 | SENTINEL | not readable | not readable | · | no |
| 2 | DC RECYCLED V1 | not readable | not readable | · | no |
| 3 | DC ROYAL RED | 45 | 50 | gbp zuerst | yes |
| 4 | REDHOOD ARKHAM | 80 | 65 | gbp zuerst | yes |
| 5 | JOKER | 40 | 30 | eur zuerst | no |
| 6 | SPIDER-MAN 2099 | 45 | 35 | gbp zuerst | no |
| 7 | REDHOOD BATTLE DAMAGED | 80 | 65 | gbp zuerst | no |
The model counted 7 tags in the scored area. The answer key is deliberately not shown beside it, otherwise a later model could read it off this page.
The model on the hardest part, quoted in the German it answered in: „Die kleinen, teils schräg oder um 90° gedrehten Preisschilder in Bild B, besonders die zweizeiligen Aufkleber mit zwei Währungen in unterschiedlicher Lesbarkeit (SPIDER-MAN 2099 und REDHOOD BATTLE DAMAGED). Bei Bild A war die Zahl in Klammern im Titel der mittleren Kachel (VS. OPUS 4.5) sowie die kleinen Modellnamen am rechten Rand des Diagramms am schwersten zu lesen.“
Where the model called itself unsure (7 places)
- Kacheltitel 'VS. OPUS 4.5 (40,8)' — Klammerwert nicht sicher abgelesen, aus Kontext erschlossen
- Sentinel-Schild in Bild B — Name nur erahnt, Preis nicht gelesen
- DC RECYCLED V1 — kein Preis lesbar
- REDHOOD BATTLE DAMAGED — Zahlenzuordnung 80/65 nicht völlig sicher
- SPIDER-MAN 2099 — £45/€35 und deren Reihenfolge wegen Drehung unsicher
- Diagrammpunktbezeichnungen rechts (Gemma 3.5 9B, Qwen3 Next 80B (reasoning), Opus 4.5 vs. Opus 4.6 Lage) — beim Nachbau teils nur annähernd sicher
- Dashed-Line-Beschriftung am Tooltip ('Opus 4.5 – 46,8'?) — im Nachbau weggelassen
The model wrote this list itself, not the scorer, and in German; it is quoted as written. It counts: an admitted “not readable” costs one point, an invented entry costs more.
The complete answer of the model as JSON · The scoring is not published beside it: it names the correct value for every mistake, which would put the answer key in the open.
Run: Moorhuhn · Halogen · W4B · reasoning xhigh · 14 September 2026
The numbers at a glance
Decode, median
38.28 t/s
652 scored responses
Decode, p10 to p90
33.08–43.65 t/s
As with the llama.cpp runs, responses from 200 tokens up are scored. Classic median, percentiles by rank. Halogen writes one line per response with tokens, time and rate; the rate the server reports is what is scored. This threshold does NOT apply to prefill, every response counts there: the new prompt tokens divided by the reported prefill time. Next to it stands the median from 8,192 new tokens up; the table in the speed section shows how the rate rises with the number of new tokens.
Peak
61.80 t/s
a single response
Prefill from 8,192 new tokens
1120.7 t/s
median over 39 requests, 35 of them above 1,000 t/s
Prefill over all requests
347.9 t/s
median over 891 answered requests; a request added 654 new tokens in the median
Output generated
1,144,717 Token
scored responses only, from 200 tokens up
Runtime
11.7 h
703 minutes
Self-corrections
not measured
Responses in total
891
652 of them scored; 917 requests sent
Input in total
50.51 Mio. Token
the context of all 891 answered requests added up
of that newly computed
2,862,509 Token
47.65 million were in the prompt cache
Through the model in total
51.69 Mio. Token
input and output together
Halogen 0.6.3 server log, written through a proxy · 652 of 891 responses from 200 tokens up · run of 14/15 September 2026. The log starts on 14 September at 15:32:17 and ends on 15 September at 10:13:53, which is 1,121.6 minutes. Between the end of a response and the next request it contains seven pauses over 60 seconds, 418.3 minutes in total, the longest 292.9 minutes during the night. The working window is therefore 703 minutes. Pure compute time on the server is 634.9 minutes. · Raw log
Results
Moorland Mayhem – Federsturm
Opens in its own layerLeft click or space fires, right click or R reloads, Escape pauses.
Loads only on click · 0.3 MB transfer · 1.7 MB unpacked
Decode over context depth
A peak figure at short context says little about how a model feels after hours. Hence the curve.
Context depth in thousands of tokens · The 652 scored responses sorted by prompt size and split into six equally sized groups; each point is the median prompt size and the median speed of its group. Measured between 729 and 143,082 tokens of context. 268 of these responses ran next to a second request, Halogen serves two slots. Every point can be traced in the linked server log.
Prefill by new tokens per request
For every request Halogen logs the prompt tokens, the part of them served from the cache and the prefill time. The rate is the number of new tokens divided by that time. In agent work a request brings only 654 new tokens in the median, and requests with 32 to 511 new tokens already took 1.46 s in the median. That is why the median over all 891 answered requests is 347.85 t/s, but 1,120.69 t/s from 8,192 new tokens up.
| New tokens per request | Requests | Timemedian | Ratemedian |
|---|---|---|---|
| 1 to 31 | 16 | 0.06 s | 83.33 t/s |
| 32 to 511 | 372 | 1.46 s | 175.38 t/s |
| 512 to 2,047 | 351 | 2.13 s | 436.14 t/s |
| 2,048 to 8,191 | 113 | 4.04 s | 761.70 t/s |
| 8,192 to 32,767 | 20 | 16.07 s | 1092.83 t/s |
| 32,768 and more | 19 | 70.48 s | 1171.72 t/s |
All 891 answered requests split into six bands by their number of new tokens, time and rate as the median of each band. Traceable in the serve_api lines of the linked server log; parse_logs.py in the evidence repository prints the bands and the figure from 8,192 new tokens up.
Server configuration
- Server
- halogen-flash-server 0.6.3
- Container
- ghcr.io/peonist-ai/halogen-flash-server:0.6.3
- Weights
- W4B with quality overlay, 741 tensors, 2.40 GiB
- Context
- 262,144 per request, one KV pool for two slots
- Speculative
- MTP at depth 1, only while no second stream runs, plus prompt lookup (pld in the log)
- Reasoning
- xhigh
- Sampling
- temp 1.0 · top_p 0.95 · top_k 20 · min_p 0.0 · presence 0.0, only for fields the request does not set
- Vision
- on
- Memory
- 68.0 GiB of weights locked in RAM, 7.2 GiB KV pool, 21.1 GiB working memory
- Lookup table
- 47.7 GiB, read from disk as needed
- iGPU
- 2.0 GiB reserved for the iGPU in firmware
- System
- Linux
  Halogen Qwen3.8-Flash-Next W4B + Qualitaets-Overlay + Vision  (ghcr.io/peonist-ai/halogen-flash-server:0.6.3)

  Kontext  : 262144 je Request, KV-Pool 262144 Positionen, 2 Slot
  Budget   : max_tokens-Default 65536 je Anfrage, Cap 262144, Slots 2
  Reasoning: xhigh, getrennt in reasoning_content
  Sampling : temp 1.0  top_p 0.95  top_k 20  min_p 0.0  presence 0.0  (nur fuer fehlende Felder)
  Cache    : Prompt-Cache 2, Queue-Timeout 28800 s
  Vision   : an (qwen38-flash-next-vision.hgn)
  RAM      : 123 GiB sichtbar, 13 GiB belegt, 1179 freie 2-MiB-Bloecke
  Endpoint : http://127.0.0.1:18099/v1 (VS Code ueber Live-Log-Proxy :8099)   Modell: halogen-qwen3.8-flash-next-w4b-quality-overlay
  Watchdog : 0 (0 = aus)

  Laden: gemessen 30 s (13.09., Pool 32768); bei fragmentiertem Speicher ueber 5 min.
All figures come from the header and the startup messages of the raw log. There is no launch line as with llama.cpp, Halogen runs as a container. Above is the header the start script writes into the log, verbatim.
Assessment
32 / 40
The grade is a personal, and therefore subjective, assessment.
Game feelDoes it run, and does it play?
8/10
Good feedback, it is fun to play. It could be a bit more varied, though, and feel a little more polished.
PresentationMenus, HUD, graphics, sound
9/10
There are a few rendering errors; the wings, for example, are the wrong way round. The menus and the overall design are very convincing, though.
Code qualityTests, structure, self-corrections
7/10
A few code files are too large, but otherwise the code is tidy and sticks to the prescribed structure. 169 unit tests were written for the logic. The function names fit and are easy to understand.
ScopeHow much of the prompt was fulfilled?
8/10
The game was implemented extensively. Individual features are buggy, e.g. the precision bonus is not applied and the volume slider cannot be dragged.
How do you see it? The grade above is a personal assessment. Here yours counts, independently of it.
What went wrong
- At startup the server reported 13.7 GiB of memory already in use and warned that prefill could therefore run several times slower than published, with pauses of a minute or more.
- 15 requests ended with HTTP 400 without a single token, 14 of them between 16:11 and 16:13. At 17:08 another one ended with HTTP 504.
- Seven responses ran into their limit of 8,192 tokens between 17:28 and 18:50 and were cut off there.
- Between 23:46 and 00:18 the server aborted three requests: twice because the engine delivered nothing for 300 seconds during decode, once for 1,800 seconds during prefill.
- At 07:31 and at 07:38 VS Code closed the connection in the middle of a response.
- At 08:22 the server refused two requests: three images were announced, none arrived.
- The number of messages per request drops back to seven or fewer 25 times in the log, the last time at 08:33, from 311 to 7.
Halogen 0.6.3 server log, written through a proxy · 652 of 891 responses from 200 tokens up · run of 14/15 September 2026. The log starts on 14 September at 15:32:17 and ends on 15 September at 10:13:53, which is 1,121.6 minutes. Between the end of a response and the next request it contains seven pauses over 60 seconds, 418.3 minutes in total, the longest 292.9 minutes during the night. The working window is therefore 703 minutes. Pure compute time on the server is 634.9 minutes.
Image recognition
Repeated on 18 September 2026 with the original images and the benchmark's own agent, not part of the run that built the game. The first test of 17 September is invalid: it got a scaled-down version of image B and ran in VS Code's built-in agent mode.
Values read
42 of 50
dashboard, 50 checkable entries
Price tags
1 of 4
read fully correctly
Invented tags
2
1 of them claimed as certain
Stumbling points spotted
3 of 4
places that break the pattern
Provisional: the answer key for the price tags is not fully confirmed yet.
Task 1 · reading values
What the model read from the tooltip table
| Claude Opus 4.5 | Qwen3.6 27B | |
|---|---|---|
| Intelligence Index | 40.8 | 37.1 |
| GPU Diamond | 87 | 84 |
| Humanity's Last Exam | 29 | 72 |
| Terminal-Bench 2.0 | 50 | 61 |
And from the KPI tiles, in German as on the test image
- QWEN3.6 27B 37.1 · AA Intelligence Index — Open-Weight, kein API-Key, läuft auf deiner eigenen GPU.
- VS. OPUS 4.5 (40,7) 91% · des Opus-4.5-Niveaus im Gesamtrating. Bei Coding-Benchmarks: gleichauf.
- PROPRIETÄRE SPITZE · HEUTE 59.9 · Das Rechenzentrum klettert weiter — doch der Abstand schrumpft jedes Quartal.
Task 2 · complex text recognition
What is tested is the reading of tiny, tilted, partly hidden text in a photo with more than forty objects, plus two currency symbols that are hard to tell apart once rotated. The price tags are what the test is run on.
What the model read
| What the model read there | £ | € | Order | certain | |
|---|---|---|---|---|---|
| 1 | REDHOOD OVI | 30 | 40 | gbp zuerst | yes |
| 2 | RED HOOD INFERNO | 60 | 65 | gbp zuerst | yes |
| 3 | REDHOOD BADLAND DAMAGED | 80 | 95 | gbp zuerst | no |
| 4 | REDHOOD BATTLE DAMAGED | 80 | 95 | gbp zuerst | no |
| 5 | JOKER | 30 | 40 | gbp zuerst | yes |
| 6 | UNHOLLOWED | 45 | 35 | gbp zuerst | no |
The model counted 6 tags in the scored area. The answer key is deliberately not shown beside it, otherwise a later model could read it off this page.
The model on the hardest part, quoted in the German it answered in: „Die winzige Tooltip-Fußnote und die feinen Datenpunkt-Beschriftungen im Diagramm (z. B. das kleine 'Opus 4.5 · 40.8' rechts); bei Bild B die Unterscheidung von 'BADLAND' vs. 'BATTLE DAMAGED' auf zwei nahezu identischen roten Helmen und die Währungszeichen auf dem weißen 'UNHOLLOWED'-Schild.“
Where the model called itself unsure (8 places)
- Tooltip-Fussnote (lautere 'AA Intelligence Index v0.6 · …', Rest unleserlich)
- Kachel 2: Klammerwert '(40,7)' — könnte '(49,7)' sein
- x-Achse: ob rechts noch ein Tick '27 existiert
- Legenden-Badges: 'open' bei Gemma und 'cloud+open' bei Mistral nicht pixelgenau bestätigt
- 'Mistral S 4' — Schreibweise des Modells nicht 100% sicher
- 'REDHOOD OVI' — könnte 'OV1' heißen
- UNHOLLOWED-Schild: Währungssymbole (£/€) nicht sicher lesbar
- Humanity's Last Exam: 72 auf der Qwen-Seite überrascht mich, ist aber so lesbar
The model wrote this list itself, not the scorer, and in German; it is quoted as written. It counts: an admitted “not readable” costs one point, an invented entry costs more.
The complete answer of the model as JSON · The scoring is not published beside it: it names the correct value for every mistake, which would put the answer key in the open.
Run: Clair Obscure · UD-Q4_K_XL · reasoning xhigh · 01 September 2026
The numbers at a glance
Decode, median
10.93 t/s
92 scored responses
Decode, p10 to p90
9.70–13.85 t/s
Responses from 200 tokens up are scored; shorter ones produce outliers of over 1,000,000 t/s in the log, because a single token there takes almost zero milliseconds. Classic median, percentiles by rank. This threshold does NOT apply to prefill, where every evaluation counts.
Peak
17.01 t/s
a single response
Prefill, median
109.7 t/s
Output generated
236,460 Token
scored responses only, from 200 tokens up
Runtime
6.2 h
370 minutes
Self-corrections
not measured
Responses in total
106
92 of them scored
Input in total
8.15 Mio. Token
the context of all 106 requests added up
of that newly computed
251,883 Token
7.90 million were in the prompt cache
Through the model in total
8.39 Mio. Token
input and output together
At a hosting provider
0.29 USD
Qwen3.8 Flash hosted, cheapest rate
What this run would have cost with Qwen3.8 Flash at a hosting provider
| Provider | Inputper M | Outputper M | Cacheper M | This runwithout cache | This runwith cache |
|---|---|---|---|---|---|
| Alibaba Cloud Int. | 0.15 | 0.47 | 0.016 | 1.34 | 0.29 |
All amounts in USD. The first three columns are tariffs per million tokens, the last two are the total for this run. Calculated with the same tokens as on the left: 8,153,803 input across all requests, of which 251,883 were newly computed and 7,901,920 came from the prompt cache, plus 238,371 output. The “without cache” column charges the entire input at the input rate. In the “with cache” column, the new part pays the write rate of 0.20 USD and the cached part the read rate of 0.016 USD. The only provider is Alibaba Cloud International. There the model is called “Qwen3.8 Flash”, without the suffix Next and without a parameter count. What ran here is the Qwen3.8-Flash-Next build from Hugging Face with 125 billion parameters, 6 billion of them active. The same vendor, the same context length of 1,000,000 tokens and the same release date point to the same origin; the provider page does not prove it. As of 8 September 2026, list prices without volume discounts. Locally, the run costs electricity and the purchase of the computer instead. Prices at OpenRouter, retrieved 2026-09-08.
What this run would have cost with Sonnet 5 at the same token consumption
| Model | Inputper M | Outputper M | Cache writeper M | Cache readper M | This runwithout cache | This runwith cache |
|---|---|---|---|---|---|---|
| Sonnet 5 | 2.00 | 10.00 | 2.50 | 0.20 | 18.69 | 4.59 |
All amounts in USD. The first four columns are tariffs per million tokens, the last two are the total for this run. Calculated with exactly the tokens of this run: 8,153,803 input, of which 251,883 new and 7,901,920 from the cache, plus 238,371 output. Without cache at the input rate; with cache, the new part pays the write rate and the cached part the read rate. This is a comparison that assumes the same token consumption. A different model solves the same task with a different number of tokens, usually fewer; so the row says what these tokens would have cost with Sonnet 5, not what Sonnet 5 would have cost for this task. Anthropic price list, retrieved 2026-09-08.
llama.cpp server log · 92 of 106 responses from 200 tokens up · run from August 2026. The server ran for 374.4 minutes in one go. From the first task to the end of the last one it is 369.7 minutes, without a single pause of more than 60 seconds in between. Pure compute time on the GPU is 368.1 minutes. · Raw log
Results
Clair Obscur Echo — Studio of the Gilded Hour
Opens in its own layerMouse and keyboard. Enemy attacks are announced, parrying and dodging happen in real time. Needs WebGL.
Loads only on click · 0.3 MB transfer · 1.7 MB unpacked
Prefill over context depth
A peak figure at short context says little about how a model feels after hours. Hence the curve.
Context depth in thousands of tokens · Instantaneous rate within a single continuous prefill: task 176155 of this run processed 35,009 tokens in one go. llama.cpp reports an intermediate status every 2,048 tokens; the rate is the quotient of tokens and time between two consecutive reports. 15 steps remain; leftover pieces under 1,500 tokens are discarded, because there the call overhead is measured rather than depth. From 2,048 to 33,642 tokens the rate drops by a factor of 1.19. Every point can be recalculated from the linked server log.
llama.cpp launch parameters
- Context
- 262,144
- KV-Cache
- q8_0 / q8_0
- Micro-Batch
- 512
- Speculative
- MTP, older version (not the one from Unsloth)
- Build
- 580e88d
llama-server -m Qwen3.8-Flash-Next-UD-Q4_K_XL-00001-of-00004.gguf ^
  --mmproj mmproj-F16.gguf --alias qwen3.8-flash-next ^
  --host 127.0.0.1 --port 8099 --device Vulkan0 ^
  --gpu-layers all --n-cpu-moe 0 --fit off -fa on ^
  --load-mode mmap --lazy-mode on ^
  --ctx-size 262144 --parallel 1 --kv-unified ^
  -ctk q8_0 -ctv q8_0 -b 2048 -ub 512 ^
  --ctx-checkpoints 4 --checkpoint-min-step 4096 ^
  --jinja --reasoning on --reasoning-format deepseek --reasoning-effort xhigh
Assessment
22 / 40
The grade is a personal, and therefore subjective, assessment.
Game feelDoes it run, and does it play?
6/10
Combat arena runs, parrying and dodging are in place.
PresentationMenus, HUD, graphics, sound
6/10
Recording available.
Code qualityTests, structure, self-corrections
4/10
No test files; no repair scripts either.
ScopeHow much of the prompt was fulfilled?
6/10
29 files, 6,157 lines.
This assessment is a proposal and has not yet been confirmed by Kai Bennett. Code quality and scope rest on counted files, source and test lines and repair scripts in the evidence repository.
How do you see it? The grade above is a personal assessment. Here yours counts, independently of it.
What went wrong
No self-corrections were logged.
llama.cpp server log · 92 of 106 responses from 200 tokens up · run from August 2026. The server ran for 374.4 minutes in one go. From the first task to the end of the last one it is 369.7 minutes, without a single pause of more than 60 seconds in between. Pure compute time on the GPU is 368.1 minutes.
Image recognition
This run has no image recognition test of its own. Shown is the one from the run “Moorhuhn · UD-Q4_K_XL · reasoning xhigh”.
Repeated on 18 September 2026 with the original images, not part of the run that built the game. The first test that morning is invalid: it got a scaled-down version of image B, and the agent's tool restriction did not take effect.
Values read
41 of 50
dashboard, 50 checkable entries
Price tags
2 of 4
read fully correctly
Invented tags
4
1 of them claimed as certain
Stumbling points spotted
1 of 4
places that break the pattern
Provisional: the answer key for the price tags is not fully confirmed yet.
Task 1 · reading values
What the model read from the tooltip table
| Claude Opus 4.5 | Qwen3.6 27B | |
|---|---|---|
| Intelligence Index | 40.8 | 37.1 |
| GPQA Diamond | 87 | 84 |
| Humanity's Last Exam | 29 | 22 |
| Terminal-bench 2.0 | 50 | 61 |
And from the KPI tiles, in German as on the test image
- QWEN3.6 27B 37.1 · AA Intelligence Index — Open-Weight, kein API-Key, läuft auf deiner eigenen GPU.
- VS. OPUS 4.5 (40,8) 91% · des Opus-4.5-Niveaus im Gesamtindex. Bei Coding-Benchmarks gleichauf.
- PROPRIETÄRE SPITZE - HEUTE 59.9 · Das Rechenzentrum klettert weiter — doch der Abstand schrumpft jedes Quartal.
Task 2 · complex text recognition
What is tested is the reading of tiny, tilted, partly hidden text in a photo with more than forty objects, plus two currency symbols that are hard to tell apart once rotated. The price tags are what the test is run on.
What the model read
| What the model read there | £ | € | Order | certain | |
|---|---|---|---|---|---|
| 1 | SENTINEL | not readable | not readable | · | no |
| 2 | DC RECYCLED V1 | not readable | not readable | · | no |
| 3 | DC ROYAL RED | 45 | 50 | gbp zuerst | yes |
| 4 | REDHOOD ARKHAM | 80 | 65 | gbp zuerst | yes |
| 5 | JOKER | 40 | 30 | eur zuerst | no |
| 6 | SPIDER-MAN 2099 | 45 | 35 | gbp zuerst | no |
| 7 | REDHOOD BATTLE DAMAGED | 80 | 65 | gbp zuerst | no |
The model counted 7 tags in the scored area. The answer key is deliberately not shown beside it, otherwise a later model could read it off this page.
The model on the hardest part, quoted in the German it answered in: „Die kleinen, teils schräg oder um 90° gedrehten Preisschilder in Bild B, besonders die zweizeiligen Aufkleber mit zwei Währungen in unterschiedlicher Lesbarkeit (SPIDER-MAN 2099 und REDHOOD BATTLE DAMAGED). Bei Bild A war die Zahl in Klammern im Titel der mittleren Kachel (VS. OPUS 4.5) sowie die kleinen Modellnamen am rechten Rand des Diagramms am schwersten zu lesen.“
Where the model called itself unsure (7 places)
- Kacheltitel 'VS. OPUS 4.5 (40,8)' — Klammerwert nicht sicher abgelesen, aus Kontext erschlossen
- Sentinel-Schild in Bild B — Name nur erahnt, Preis nicht gelesen
- DC RECYCLED V1 — kein Preis lesbar
- REDHOOD BATTLE DAMAGED — Zahlenzuordnung 80/65 nicht völlig sicher
- SPIDER-MAN 2099 — £45/€35 und deren Reihenfolge wegen Drehung unsicher
- Diagrammpunktbezeichnungen rechts (Gemma 3.5 9B, Qwen3 Next 80B (reasoning), Opus 4.5 vs. Opus 4.6 Lage) — beim Nachbau teils nur annähernd sicher
- Dashed-Line-Beschriftung am Tooltip ('Opus 4.5 – 46,8'?) — im Nachbau weggelassen
The model wrote this list itself, not the scorer, and in German; it is quoted as written. It counts: an admitted “not readable” costs one point, an invented entry costs more.
The complete answer of the model as JSON · The scoring is not published beside it: it names the correct value for every mistake, which would put the answer key in the open.
Sources
- Model weightshuggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF
- Model cardhuggingface.co/Qwen/Qwen3.8-Flash-Next
- Vendor siteqwen.ai
- Measurement repositorygithub.com/KaiFelixBennett/local-ai-amd-benchmark
- Raw log of this rungithub.com/KaiFelixBennett/local-ai-amd-benchmark/blob/main/evidence/logs/qwen38-flashnext-moorhuhn-evox2.log
- Source code · Moorhuhn · UD-Q4_K_XL · Reasoning xhighgithub.com/KaiFelixBennett/local-ai-amd-benchmark/tree/main/benchmarks/qwen38-flashnext/moorhuhn-q4xl
- Source code · Moorhuhn · Halogen · W4B · Reasoning xhighgithub.com/KaiFelixBennett/local-ai-amd-benchmark/tree/main/benchmarks/qwen38-flashnext/moorhuhn-halogen
- Source code · Clair Obscure · UD-Q4_K_XL · Reasoning xhighgithub.com/KaiFelixBennett/local-ai-amd-benchmark/tree/main/benchmarks/qwen38-flashnext/clairobscure-q4xl
- Halogen servergithub.com/peonist-ai/halogen-flash-server
- Weights for Halogenhuggingface.co/peonist-ai/halogen-qwen3.8-flash-next
Try it yourself
- Download the weights · Source
- Start llama-server with the parameters above
- Register the endpoint in VS Code as a custom model and pick the agent
Prompt, agent files and tools: Agent Test Harness
Citation: Kai Felix Bennett, “Usability test of local AI on AMD hardware”, benchmark.securesight.ai, run qwen38-flashnext-moorhuhn-evox2. Measurement data CC-BY-4.0.
Measurement data CC-BY-4.0, code MIT.